
LLMVisExplorer: Visually exploring the knowledge landscape of large language models
Abstract
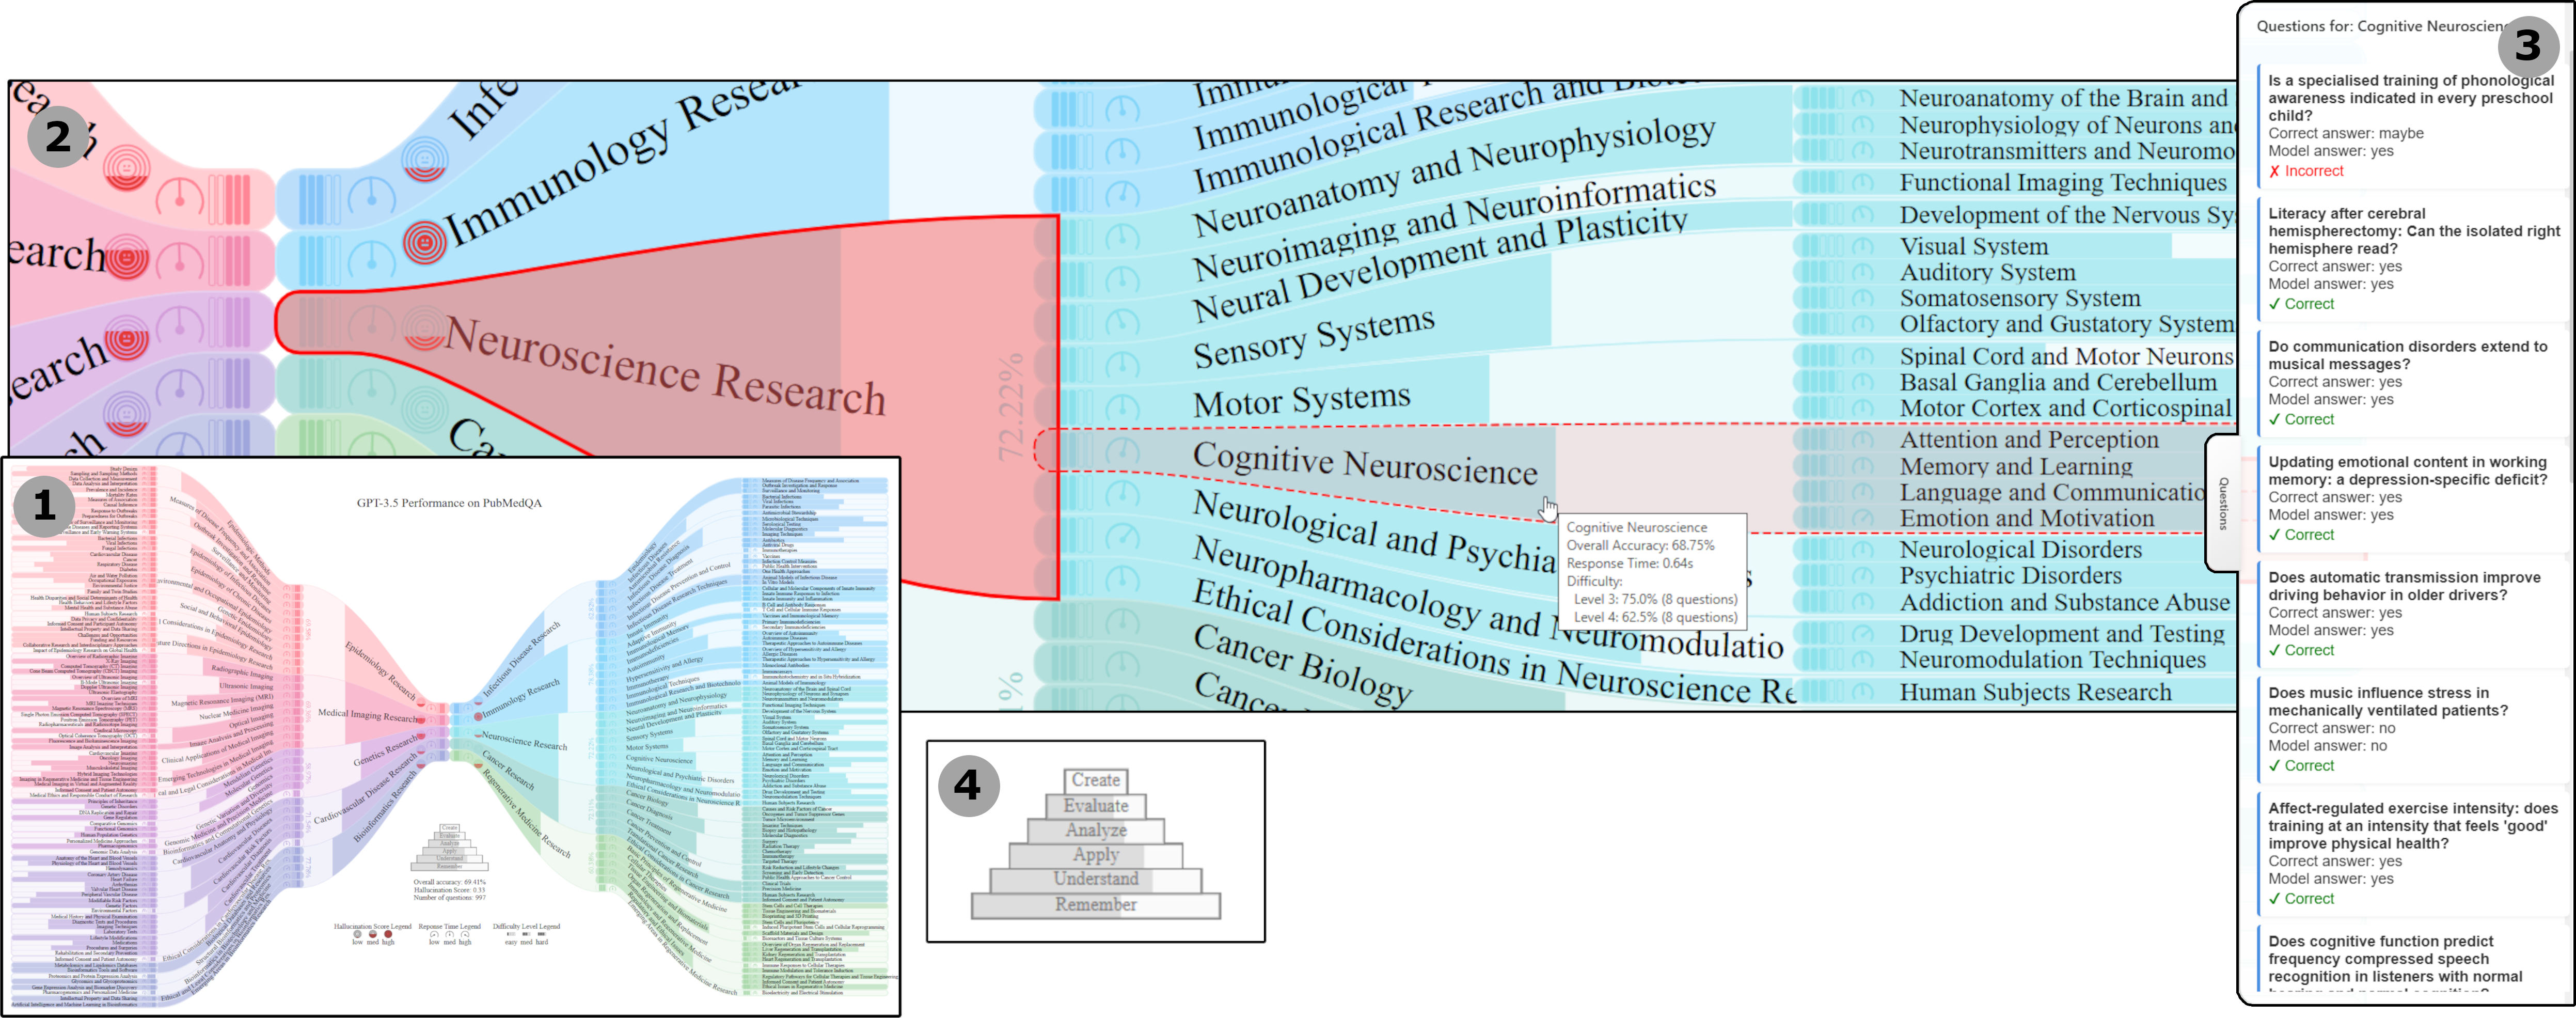
The performance of large language models (LLMs) in specific knowledge domains is often evaluated based on question and answer (Q\&A) benchmark datasets. Although benchmark reports sometimes include domain-level breakdowns, evaluation results are still frequently summarized through aggregate accuracy values or coarse tables that make it difficult to inspect multi-level, multi-metric, and question-level performance variation. This is problematic because Q\&A benchmark datasets are by design diverse and span broad domains, such as science (SciQ) or biomedicine (PubMedQA). We argue that overly coarse evaluation summaries can collapse meaningful details: strong performance in easier or overrepresented areas can overshadow weaknesses in critical or complex subdomains, making such summaries insufficient for downstream use. To enable better understanding of real-world model capabilities essential for downstream applications, we propose LLMVisExplorer, an interactive visualization system that facilitates in-depth evaluation of LLM performance within the subdomains of complex knowledge domains. Based on LLM evaluation design requirements grounded in the natural language processing (NLP) literature, LLMVisExplorer bridges the gap between coarse-grained benchmark reporting and actionable model insights by enabling multifaceted, visually guided performance analysis across hierarchical knowledge domains. It empowers both, LLM developers and LLM users, to identify domain-specific strengths and weaknesses, in order to inform model development, red-teaming, and deployment decisions. We discuss LLMVisExplorer's design requirements as well as its realization, and showcase its potential on several use cases evaluating single models as well as comparing multiple models, such as Claude 3.5 Sonnet, GPT-4o, and Yi-large.
BibTeX
@article{poonam2026llmvisexplorer,
	title={LLMVisExplorer: Visually exploring the knowledge landscape of large language models},
	author={Poonam, Poonam and Puchert, Patrik and Ribalta-Albado, Maria and van Onzenoodt, Christian and Viola, Ivan and V{\'a}zquez, Pere-Pau and Ropinski, Timo},
	year={2026},
	journal={Computer & Graphics}
}